🔍 Read the full analysis: 5 Ways To Use NVIDIA Warp And MjWarp For Robotics Simulation And Learning on ThorstenMeyerAI.com

Get the latest gadgets delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
TL;DR
Hugging Face’s second article in its physical AI simulation series walks through preparing an SO-101 robot arm simulation with MuJoCo Warp (MJWarp). It demonstrates up to 2,048 parallel environments, but does not report a measured speedup, train a robot policy or show that the workflow improves learning results.
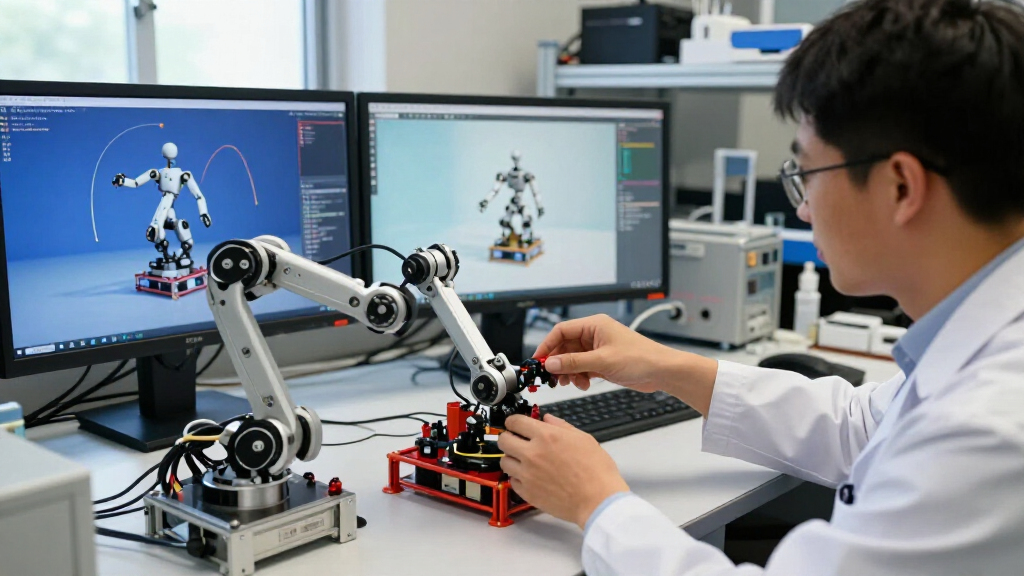
Hugging Face’s second article in its State of Simulation for Physical AI series shows how to move an SO-101 follower arm from a standard MuJoCo workflow into MuJoCo Warp (MJWarp), demonstrating up to 2,048 parallel environments, as outlined in the original analysis. The tutorial focuses on preparing and scaling the simulation; it does not report a measured speedup or train a robot policy.
The guide describes a division of work between the two simulation tools. MuJoCo loads and compiles the robot’s MJCF model, while MJWarp implements compatible MuJoCo physics with kernels from NVIDIA Warp, which can be compiled to run on NVIDIA GPUs. The example uses an SO-101 model and task geometry from available robot assets.
The environment count is a scale demonstration, not a throughput result. The supplied material gives no simulation rate, GPU model or comparison baseline for the 2,048-world example. Without those details, readers cannot tell how quickly the environments advance or compare the setup with a CPU workflow under the same conditions.
Hugging Face draws a clear boundary around the walkthrough: “Here, we prepare and scale the simulation environment; we do not train a policy.” The article explains setup and GPU execution, rather than reporting task success, training time or evidence that the workflow improves a learned controller.
When Batched Simulation Helps
Running many copies of a scene at once can help robot-learning work that needs experience from varied starting states or many candidate actions. MJWarp’s batched GPU approach gives teams a way to explore that setup while keeping simulation data near the accelerator. It addresses a practical engineering question: how to scale a familiar robot model across multiple simulated worlds.
The best choice depends on the task. The source recommends CPU MuJoCo for single-robot model-predictive control or teleoperation, and MJWarp or mjlab when the priority is raw MuJoCo physics throughput. For JAX-oriented training recipes, it points to MuJoCo Playground or MJX with the Warp implementation. Teams looking for a broader multi-solver API and Isaac Lab integration are directed to Newton, which the series plans to cover later.
These options are guidance, not results from a head-to-head test in the SO-101 tutorial. The 2,048-environment figure alone does not establish frame rate, hardware cost, compatibility across robot models or the quality of experience produced for learning.
From MJCF to GPU Kernels
MuJoCo is used for robot simulation and control, including workloads that distribute sampling across CPU cores. In the tutorial’s stack, Warp supplies the kernel language and device execution, while MJWarp supplies compatible MuJoCo physics. The workflow links those tools to the SO-101 model and its simulated task.
Warp is a framework for writing kernels in Python for GPU or CPU execution. The guide says a first kernel launch compiles and caches a native module, with later launches reusing it. It also warns that copying a CUDA array into NumPy synchronizes execution and transfers data to the CPU. Keeping data on the device requires framework adapters or DLPack-compatible sharing.
This is the series’ second installment, following an overview of robot simulation. Hugging Face frames it as a preparation and scaling exercise, with later articles on Newton and Isaac Lab intended to address further integration layers. The supplied source does not specify the article’s publication date.
““Here, we prepare and scale the simulation environment; we do not train a policy.””
— Hugging Face, describing the tutorial’s scope
Benchmark and Compatibility Gaps
The supplied material does not identify the GPU, workload settings or measured simulation rate behind the 2,048-environment demonstration. It also provides no comparison baseline, so the scale figure cannot be read as a speedup over CPU MuJoCo or another GPU implementation.
It remains unclear how performance changes with different robot scenes, contact conditions or hardware, and which models might need modifications to run with MJWarp. The article refers to compatible models rather than claiming every MuJoCo model will work unchanged. It also reports no policy results or task success rates. Warp’s differentiable kernels and deterministic execution are framework capabilities; they do not mean every MJWarp rollout is differentiable or deterministic by default.
From Setup to Training Evidence
Hugging Face says later installments will cover Newton and Isaac Lab, including topics such as multi-solver APIs, USD, sensors, managers and training loops. Those articles are expected to address how a prepared simulation connects with larger robotics and learning systems.
For teams weighing the workflow, the next useful evidence would include reproducible throughput measurements with hardware and task details, guidance on model compatibility, and results from an actual policy-training run. Those measurements and results are not included in the supplied material, so the tutorial establishes an implementation path rather than a performance verdict.
Key Questions
What does the Hugging Face tutorial demonstrate?
It shows how to prepare an SO-101 follower arm simulation with MuJoCo and scale it using MJWarp, with up to 2,048 parallel environments demonstrated.
Does the article show that MJWarp is faster?
No measured speedup is reported. The supplied material gives no simulation rate, hardware configuration or comparison baseline for the environment count.
Does the tutorial train a robot policy?
No. Hugging Face says the article prepares and scales the simulation environment; it does not include policy training or task results.
When might a team use CPU MuJoCo instead?
The source recommends familiar CPU MuJoCo for single-robot model-predictive control or teleoperation. It points to MJWarp or mjlab when raw MuJoCo physics throughput is the priority.
Primary source: Hugging Face · via ThorstenMeyerAI.com
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.