
TL;DR

Get the latest gadgets delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
AI document processing pipelines now run entirely on local infrastructure, ensuring data privacy and operational control. This development highlights a modular, reliable architecture for enterprise use. Key components include ingestion, OCR, structured extraction, and storage, all designed for maintainability and safety.
AI document processing pipelines are increasingly designed to operate entirely on local infrastructure, from data ingestion through OCR, extraction, and storage, without leaving the premises. This approach enhances data privacy, simplifies governance, and improves operational reliability, as confirmed by recent detailed architecture disclosures.
The architecture emphasizes a modular pipeline where each component is a narrow, single-purpose CLI, such as OCR or structured data extraction, invoked as subprocesses. The entire process is orchestrated through a PostgreSQL-based queue, which manages job claims, retries, and concurrency, avoiding the need for external messaging systems.
Documents are ingested via watch folders or upload endpoints, stored as raw bytes, and assigned unique content hashes for idempotency. OCR is performed using specialized models, with the choice of model routing based on document type and input quality. Extracted data is validated against schemas, with failures routed to review queues, ensuring high accuracy and auditability.
Implications of Localized AI Document Pipelines for Data Privacy and Operations
This architecture allows organizations to maintain full control over sensitive data, reducing reliance on cloud providers and third-party services. It simplifies compliance with regulations like the AI Act and data governance standards, while also enabling more reliable and maintainable systems. The design principles promote modularity, transparency, and safety, making it easier to update or replace components without disrupting the entire pipeline.
Products Worth Considering

DJI Mini 3 Pro Fly More Vlogger Combo with DJI RC

Kindle Paperwhite 16GB (2024) – 7 Glare-Free Display, Weeks Battery Life – Black
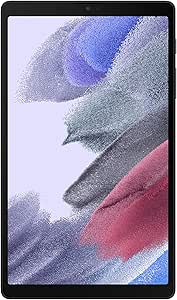
Samsung Galaxy Tab A7 Lite 8.7-Inch 32GB Wi-Fi Tablet, Gray
As an affiliate, we earn on qualifying purchases.
Evolution of AI Document Processing Systems and Industry Standards
Recent developments in AI models, including large language models and OCR systems, have shifted from cloud-based solutions to local, on-premises deployments. Industry leaders like Hugging Face have demonstrated that capable models can operate effectively on local infrastructure, driven by regulatory pressures and data privacy concerns. This architecture builds on these trends, emphasizing a pipeline that is resilient, transparent, and adaptable to future model updates.
“Designing AI pipelines that run entirely on local hardware ensures data privacy and operational safety, which are critical for enterprise adoption.”
— Thorsten Meyer, AI infrastructure expert
Remaining Questions About Scalability and Model Updates
It is not yet clear how well this architecture scales for extremely large datasets or complex document types. Additionally, the process for seamless model updates and backward compatibility across versions remains under development, with ongoing work needed to standardize version control and retraining procedures.
Next Steps for Implementing and Standardizing Local Document Pipelines
Organizations are expected to adopt this architecture for critical document workflows, with further refinements to improve scalability and model management. Industry groups may develop standards for versioning, validation, and review processes to ensure consistency across deployments. Future updates will likely focus on automation of model updates and enhanced error handling.
Key Questions
Why is local deployment of AI document pipelines important?
Local deployment enhances data privacy, simplifies governance, and reduces dependency on external cloud services, making it suitable for sensitive or regulated environments.
How does this architecture improve maintainability?
By using narrow, single-purpose CLI components and a PostgreSQL-based queue, the system is modular, easy to update, and resilient to component failures.
What are the main challenges remaining?
Scaling for large datasets, managing model version updates seamlessly, and standardizing review and validation processes are ongoing challenges.
Can this architecture support multi-language or complex document types?
Yes, but additional customization and model training are necessary to handle diverse languages and complex layouts effectively.
What is the expected timeline for broader adoption?
Organizations are beginning to implement these pipelines now, with wider industry adoption likely over the next 12-24 months as standards and tooling mature.
Source: ThorstenMeyerAI.com