🔍 Read the full analysis: How To Understand Z.ai’s Legal AI’s 1-In-5 Benchmark Performance on ThorstenMeyerAI.com

Get the latest gadgets delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
TL;DR
Z.ai’s GLM-5.3-FlashX-Legal scored 19.17% on the all-criteria task pass rate in Vals AI’s archived Harvey Legal Agent Benchmark leaderboard, placing seventh among 81 models. Vals also reported a 92.5% pass rate on individual criteria, a different measure; benchmark results do not establish that the model is reliable for unsupervised legal work.
Z.ai’s GLM-5.3-FlashX-Legal passed every required criterion on 19.17% of tasks in Vals AI’s archived Harvey Legal Agent Benchmark leaderboard, placing it seventh among 81 models. The score is an all-or-nothing measure of completed tasks, not the share of individual legal requirements the system met; Vals separately reported a 92.5% criteria pass rate.
Z.ai describes the model as designed for professional legal workflows, including document understanding, legal reasoning and task execution across research, contract review and drafting. Its developer documentation says the model underwent legal-domain mid-training and post-training, including reinforcement learning across tens of thousands of task environments modeled on legal workflows. The documentation recommends using it as an agent connected to services for laws, cases and company data.
In Z.ai’s benchmark statement, the company reported a 19.2% all-criteria pass rate and an improvement of 12.5 percentage points over the base model. The archived Vals leaderboard gives the legal model a score of 19.17% and lists the base GLM-5.3-Flash at 6.67%, a 12.50-point difference. Vals listed the legal model’s cost at $0.15 per test in that evaluation. Z.ai’s pricing page separately lists token prices of $0.37 per million input tokens and $1.25 per million output tokens; those figures are not the same metric as the leaderboard’s per-test cost.
The 19.17% represents the share of evaluated tasks on which the system passed every criterion, averaged across two AI judges, according to the supplied benchmark account. It does not mean the model met only 19.17% of all rubric criteria. Vals reported 92.5% on that separate measure, in which both judges had to pass an individual criterion. The figures describe different levels of performance and should not be substituted for one another.
Why Full-Task Pass Rates Matter
The benchmark highlights a gap between getting many details right and producing a complete work product. Harvey’s grading method treats each task as passed only when every required item meets its rubric: a missed citation, deadline, recommendation or other requirement can cause the entire task to fail. That makes the 19.17% score a strict end-to-end measure, while the 92.5% figure indicates much stronger performance at the individual-criterion level.
For law firms and legal departments, the distinction matters when judging whether a system can be trusted to produce work without close review. A high criteria rate may indicate useful performance on many parts of a task, but it does not show that a complete result is consistently ready for use. The figures support neither treating the model as incapable nor assuming it can safely handle legal work independently. Buyers still need to test it against their own workflows and set procedures for checking facts, legal authorities and client-data handling.
Cost is another point for evaluation, but the listed $0.15 per test is specific to Vals’s benchmark run. It does not establish the total cost of deploying an agent connected to legal research tools, company systems or human review. Nor does it measure the financial impact of correcting errors. Procurement comparisons need to account for those expenses alongside model performance.
Products Worth Considering

DJI Mic 3 Wireless Microphone Kit (2 Transmitters, 1 Receiver, Charging Case)
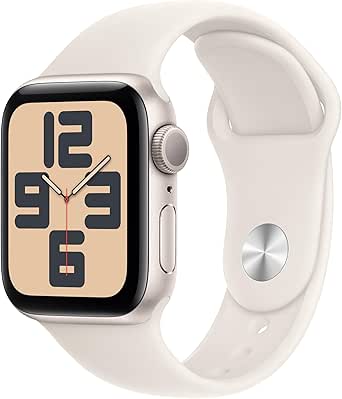
Apple Watch SE (2nd Gen) GPS 40mm with Starlight Aluminum Case and Sport Band (S/M)

Apple Watch Series 8 GPS, 41mm, Midnight Aluminum Case with Midnight Sport Band (S/M)
As an affiliate, we earn on qualifying purchases.
How Harvey Grades Legal Tasks
Harvey released its Legal Agent Benchmark as open source on May 6, 2026. The benchmark contains 1,250 tasks across 24 legal practice areas. Each task provides an instruction and client-matter materials, then asks an agent to produce work for review. Harvey says the tasks are graded against more than 75,000 expert-written, binary criteria covering items such as facts, conclusions, citations, recommendations, deadlines and formatting.
Under Harvey’s all-pass grading rule, a task counts as complete only if every criterion passes. The leaderboard uses a private holdout set, which Vals describes as 120 tasks, with internet access disabled. Two AI judges grade submissions, and the reported task score averages their pass rates. Because the score depends on the benchmark version, task set and grading process, it should be understood as a result from this particular evaluation rather than a general measure of legal capability.
Z.ai’s AutoClaw blog announcement, dated October 13, 2026, opened a beta by application and said the model is built on GLM-5.3-Flash. Vals listed the model’s release date as October 12. Z.ai called the result state of the art among open-source models in the evaluation. The source account says the company did not identify the comparison set in that statement and that no public weights for the legal model were found there, so that characterization cannot be independently assessed from the supplied information.
“A task is marked complete only if every criterion passes.”
— Harvey, describing its Legal Agent Benchmark
Limits of the Benchmark Evidence
The leaderboard result does not show how GLM-5.3-FlashX-Legal performs across all legal work, firms or jurisdictions. The reported score comes from a 120-task private holdout, and the supplied material does not provide per-task results, the full error breakdown or an independently tested comparison across every model available. The leaderboard’s 92.5% criterion figure also uses a specific judging rule that should be kept separate from task completion.
The source account reports a small, four-task spot check in which the legal model cited rulings the reviewer could not find. That check was not a benchmark and cannot establish an error rate. The same account says some other tested models cited a real ruling for a conclusion opposite to its holding, underscoring that the spot check is not enough to rank systems or establish comparative reliability.
It is also unclear from the supplied material how Z.ai handles client information when the model is used through connected services, what deployment and retention rules apply, or what review controls are built into the beta. The source account says the Z.ai pages it examined describe outputs as drafts for legal professionals and did not carry a “not legal advice” notice. These observations do not establish the terms of every deployment or the safeguards available to customers.
Questions Before Legal Deployment
Z.ai announced an application-based beta through its AutoClaw blog, but the supplied material does not give a timeline for broader access or a date for another benchmark evaluation. Prospective users will need further information about availability, deployment options and connected-service controls before assessing whether the system fits their work.
For firms testing the model, the immediate next step is to evaluate it on representative tasks using their own review standards, rather than treating a leaderboard position as a deployment decision. That review should include source verification, missed requirements, confidentiality and the cost of human checking. Until more evaluation data and product details are available, the benchmark establishes a measured result on one test—not a guarantee of safe or complete legal work.
Key Questions
What does the 19.17% score mean?
It is the share of evaluated tasks on which GLM-5.3-FlashX-Legal met every required rubric criterion, according to Vals AI’s archived leaderboard. A task with even one failed criterion does not count as passed.
Why is the 92.5% figure higher?
It measures a different thing: the share of individual criteria passed, under Vals’s reported rule that both judges had to pass each criterion. It does not mean that 92.5% of complete tasks were successful.
Is Z.ai’s improvement claim supported by the leaderboard?
The archived table lists the legal model at 19.17% and the base GLM-5.3-Flash at 6.67%. Their difference is 12.50 percentage points, consistent with Z.ai’s claim of a 12.5-point improvement on that table.
Does the result show the model is ready to handle legal work on its own?
No. The benchmark measures performance on a particular set of tasks and does not establish safe, reliable performance across legal practice. The source describes the system’s outputs as drafts for legal professionals; users would still need to verify citations and work product.
What is not yet clear about the model?
The supplied information does not fully establish its deployment and client-data terms, the extent of public access after the application beta, or how its benchmark performance varies across tasks. Z.ai’s claim of state-of-the-art open-source performance also lacks a specified comparison set in the material provided.
Source: ThorstenMeyerAI.com